Qwen3.8-Omni-Flash: 1M Context & API Pricing (2026)
Qwen3.8-Omni-Flash: Alibaba's omni-modal model, 1M-token context, $0.15/million input. Weights closed, no local run; text-only output, unlike its predecessor.
Qwen3.8-Omni-Flash is an omni-modal model that Alibaba's Qwen team announced on September 18, 2026. It accepts text, image, audio and video as input, offers a 1-million-token total context, and starts at $0.15 per million input tokens. Its weights are closed and proprietary, so it cannot be run locally.
Unlike its predecessor Qwen3.5-Omni-Plus, which could also generate audio output, Qwen3.8-Omni-Flash's output is text only. Anyone who needs a spoken response has to build their own multi-stage pipeline with an external text-to-speech engine bolted on afterward.
It is hosted on the Qwen AI platform (Tongyi/Qianwen) and Alibaba Cloud Model Studio (Bailian), both accessed via API. Below is a rundown of its specs, pricing, vendor-reported benchmarks, and how it compares with existing models.
What It Can Do — Input Modalities and Use Cases
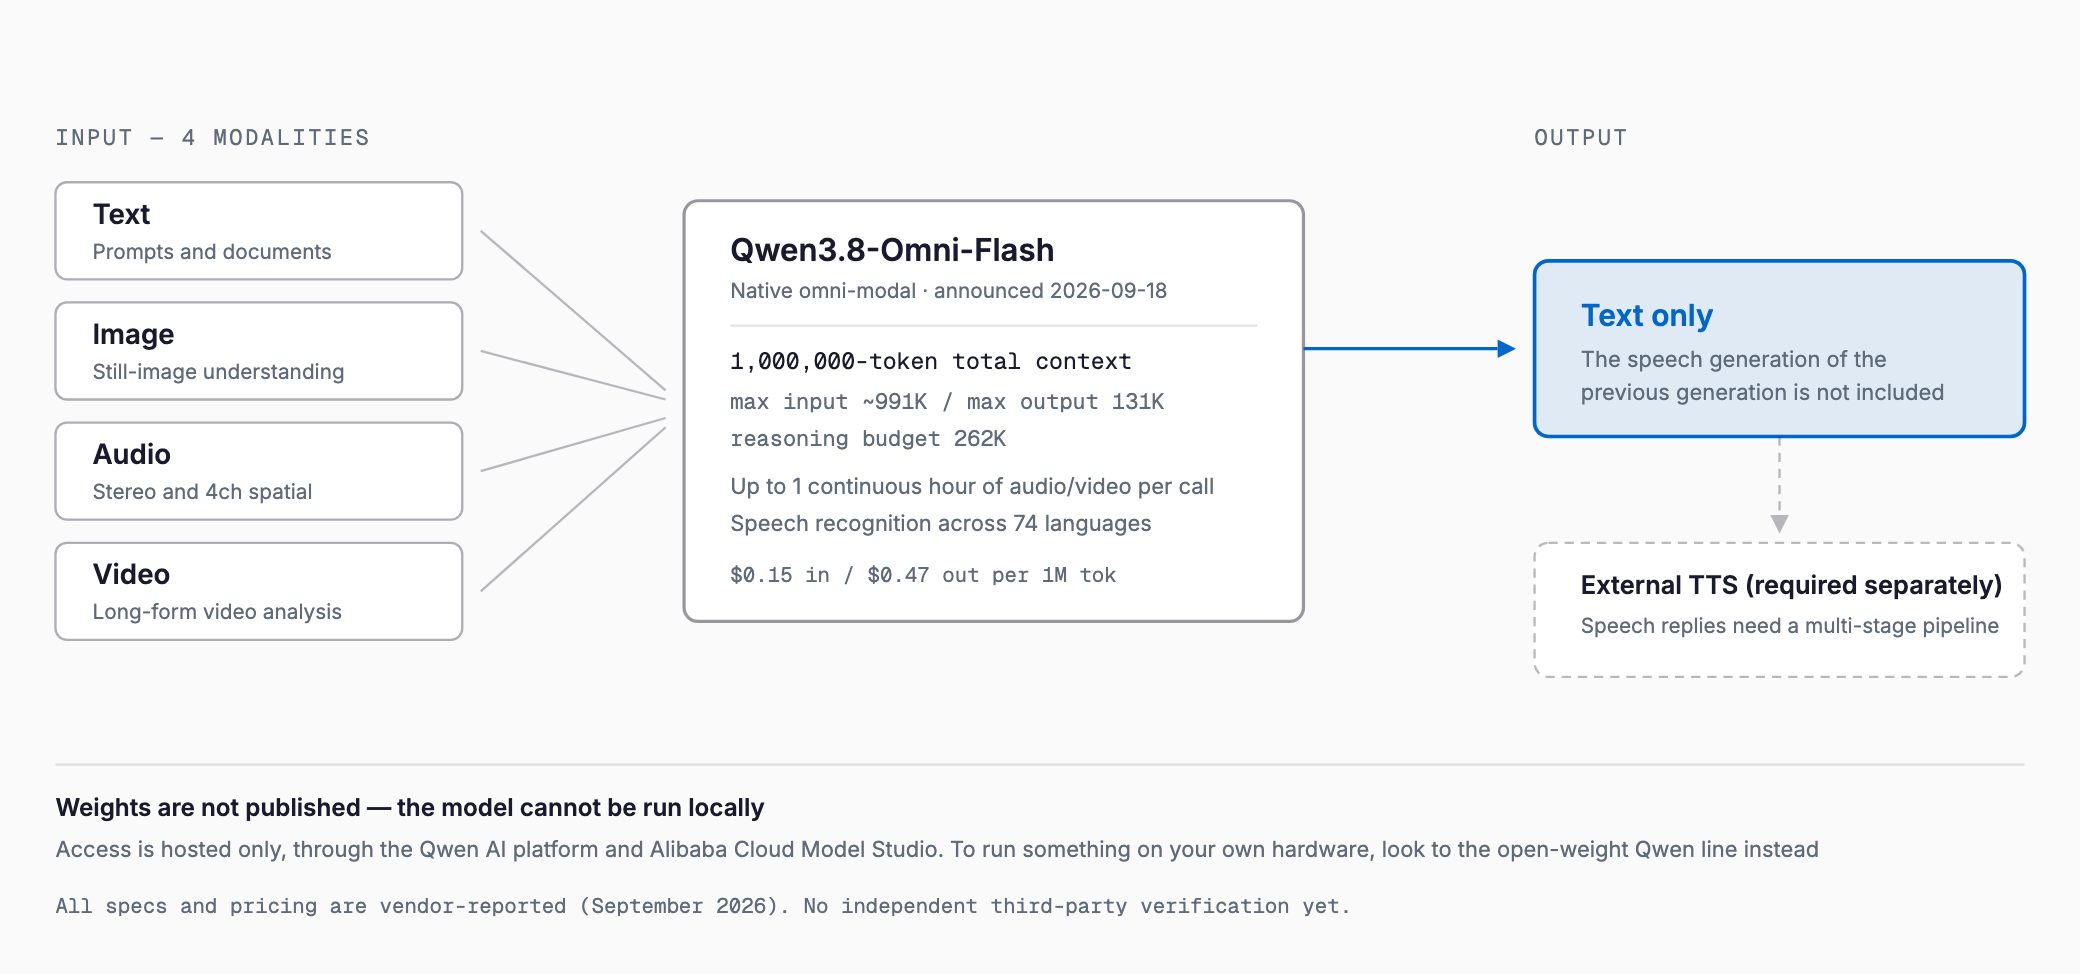
| Input modality | Examples |
|---|---|
| Text | Standard prompts and documents |
| Image | Photos, screenshots, diagram understanding |
| Audio | Speech recognition and analysis, including stereo and 4-channel spatial audio (74 languages) |
| Video | Up to one hour of continuous video per call |
- Long-video analysis (summarizing meeting recordings, surveillance footage, lecture videos)
- Meeting summarization (generating minutes and key points from audio)
- Video research (cross-referencing information across multiple videos)
- Agentic tasks involving multimodal tool use
Specifications at a Glance
| Item | Value |
|---|---|
| Release date | September 18, 2026 |
| Availability | API hosting only, on the Qwen AI platform or Alibaba Cloud Model Studio (Bailian) |
| Input modality | Text, image, audio (stereo/4-channel spatial), video |
| Output modality | Text only |
| Total context | 1,000,000 tokens |
| Max input | ~991,000 tokens (~983,000 in thinking mode) |
| Max output | 131,000 tokens |
| Reasoning budget | 262,000 tokens |
| Continuous media length | Up to 1 hour of continuous audio/video per call |
| Supported languages (speech recognition) | 74 languages (companion tools support generation in 29) |
| Weights | Closed (no local deployment) |
Pricing
| Category | Price (vendor-reported) |
|---|---|
| Input | $0.15 per million tokens |
| Cached input | $0.016 per million tokens |
| Output | $0.47 per million tokens |
| China-region (Bailian) multimodal input | ¥0.8 per million tokens (down sharply from roughly ¥18 for the predecessor) |
All figures are as published by Alibaba; actual billed rates can vary by region and contract. For a sense of pricing across the Qwen line, see our Qwen3.7-Flash API pricing guide.
Benchmarks (Vendor-Reported)
| Metric | Score | vs. predecessor (Qwen3.5-Omni-Plus) |
|---|---|---|
| Average across 30 evaluations | — | +26%+ |
| WildClawBench-MM | 71.0 | +36.5 |
| LongAudioSpan | 82.7 | +8.3 |
| OmniVideoBench | 63.4 | +9.6 |
| Token reduction in Agentic Understanding mode | -45.7% tokens per query (with improved accuracy) | — |
All of the above figures come from Alibaba; no independent third-party evaluation exists yet. Real-world performance should be verified against your own workloads. Alibaba also released Qwen-MM-Plugins and the Qwen-Live Harness alongside the model.
How to Get Started
- Issue an API key on the Qwen AI platform (Tongyi/Qianwen) or Alibaba Cloud Model Studio (Bailian)
- Send a request specifying Qwen3.8-Omni-Flash as the model (check the official docs for the current exact model ID and parameter names)
- When sending audio or video, confirm file-size limits and the one-hour continuous-media cap in advance
- Since output is text only, design a multi-stage pipeline with an external TTS engine downstream if a spoken response is needed
- For long-context workloads, keep shared system prompts or context as a fixed segment so it qualifies for cached-input pricing
How It Compares With Existing Models
| Model | Weights | Output modality | Context | Pricing tendency |
|---|---|---|---|---|
| Qwen3.8-Omni-Flash | Closed | Text only | 1M tokens | Cheap, from $0.15/million input |
| Qwen3.5-Omni-Plus (predecessor) | Closed | Text + audio | Shorter than Qwen3.8-Omni-Flash | Trails Qwen3.8-Omni-Flash on benchmark metrics (vendor-reported) |
| Gemini-family multimodal models | Closed | Varies by model/plan | Varies by model | Specific pricing and specs not confirmed for this article, so comparison is deferred |
| Local-runnable Qwen open-weight models (Qwen3.8 27B, Qwen3.8-Flash-Next) | Open | Varies by model | Varies by model | No API fees, but requires your own GPU/VRAM investment |
When to Choose It, and When Not To
- Choose it: you need to process large multimodal input — long video, meeting audio — cheaply
- Choose it: you want to use the 1M-token context to reason across multiple videos or documents
- Choose it: text-only output is sufficient for your use case (summarization, analysis, search)
- Don't choose it: you need direct spoken responses (no audio output like the predecessor, so a multi-stage pipeline is mandatory)
- Don't choose it: you need to self-host the weights or require local deployment (consider open-weight alternatives like Qwen3.8 27B or Qwen3.8-Flash-Next)
- Don't choose it: your procurement requirements mandate independently verified benchmarks (only vendor-reported figures exist so far)
Can Qwen3.8-Omni-Flash be run locally?
No. Its weights are closed and proprietary, so it can only be accessed via API through the Qwen AI platform or Alibaba Cloud Model Studio (Bailian).
Can it respond with speech?
No. Output is text only. Unlike its predecessor Qwen3.5-Omni-Plus, it does not generate audio, so a spoken response requires bolting on an external text-to-speech engine in a multi-stage pipeline.
How much does it cost?
Per Alibaba's published pricing, input is $0.15 per million tokens, cached input is $0.016, and output is $0.47. In China, Bailian's multimodal input price is ¥0.8 per million tokens, down sharply from roughly ¥18 for the predecessor.
Can the benchmark numbers be trusted?
They are all vendor-reported by Alibaba, and as of September 2026 no independent third-party evaluation exists yet. Verify performance against your own workloads before adopting it.
Qwen3.8-Omni-Flash is a strong candidate for multimodal workloads involving long audio and video, backed by its 1M-token context and low pricing. But its closed weights ruling out local deployment, and its text-only output, are constraints worth weighing carefully against your requirements before adopting it.
Feel free to contact us
Contact Us